Iterators

A loop needs the next item and has no reason to care where that item is stored. An Iterator supplies the item and keeps the storage out of sight.
Code written against an iterator works the same whether the data comes from a list, a file, a database cursor, or a computation. It asks only for the next item. That is the communication-first design Design Patterns recommends. The caller states what it needs and does not name the container’s type.
Python builds iterators into the language. Any object that
follows the iterator protocol works with
for, comprehensions, sum(),
sorted(), unpacking, and every function that takes
an iterable.
Iteration Comes Built In
Two methods make up the protocol. An iterable has
__iter__(), which returns an iterator. An
iterator has __next__(), which returns the next
item or raises StopIteration. An iterator is also
iterable. Its __iter__() returns itself, so an
iterator works anywhere code expects an iterable. The
for loop calls these methods, so you rarely call
them. Every container uses this protocol, so a function written
against an iterable stays decoupled from the container.
# basic_iteration.py
nums = [1, 2]
it = iter(nums)  # Called by a for loop
print(iter(nums) is iter(nums))  # [1]
#: False
print(iter(it) is it)  # An iterator returns itself  # [2]
#: True
print(next(it), next(it))  # What the loop calls per step
#: 1 2
try:
    next(it)
except StopIteration:
    print("StopIteration ends the loop")
#: StopIteration ends the loop
A for loop makes one iter() call,
then calls next() until the iterator raises
StopIteration. A loop absorbs
StopIteration as the normal end rather than an
error.
The is at [1] shows that calling
iter() on a list creates a new iterator each time.
The is at [2] shows that calling
iter() on an iterator returns that iterator. The
tempting call is next(nums), but
next() accepts only an iterator, and a list has no
__next__(), so that call raises a
TypeError at runtime. The type checker rejects
next(nums) before the program runs.
Written out, for x in nums: is this loop:
it = iter(nums)          # Once, before the loop
while True:
    try:
        x = next(it)     # Once per step
    except StopIteration:
        break
    ...                  # The loop body
One legacy path bypasses __iter__(). A class
that defines __getitem__() in place of
__iter__(), taking integers from zero, is still
iterable. iter() builds an iterator that calls
__getitem__() with 0, 1, 2, and so on, until
IndexError. Such a class works with
for, yet isinstance(obj, Iterable)
returns False and a parameter annotated
Iterable[T] rejects it. That is the one case where
an object a for loop accepts fails an
Iterable annotation. Write __iter__()
in new code.
Generators
You rarely write
__iter__()/__next__() by hand. A
generator writes them. A function with a
yield statement returns an iterator that produces
each yielded value in turn, pausing and resuming its own
state.
The generators in this chapter produce values without
receiving any, so Iterator[T] annotates them. That
annotation is the short form of a three-part type that also
describes what a generator receives and what it returns. Generators
covers the full form, which an Effect system needs.
Writing __iter__() as a generator makes a class
iterable:
# iterators.py
from collections.abc import Iterable, Iterator
from dataclasses import dataclass

def fibonacci(n: int) -> Iterator[int]:
    a, b = 0, 1
    for _ in range(n):
        yield a
        a, b = b, a + b

# __iter__() makes a class iterable. Often a generator:
@dataclass
class Countdown:
    start: int

    def __iter__(self) -> Iterator[int]:
        n = self.start
        while n > 0:
            yield n
            n -= 1

# A function using an iterable is decoupled from its source:
def total(numbers: Iterable[int]) -> int:
    return sum(numbers)

print(list(fibonacci(8)))
#: [0, 1, 1, 2, 3, 5, 8, 13]
print(list(Countdown(5)))
#: [5, 4, 3, 2, 1]
print(total(fibonacci(8)))  # Works on a generator
#: 33
print(total([1, 2, 3, 4]))  # and a list
#: 10
print(total(Countdown(5)))  # and a custom iterable
#: 15
total() takes an Iterable, so it
works equally well on the generator, the list, and the custom
Countdown. The figure follows one loop over
nums through the protocol, then puts
total() in the loop’s place:
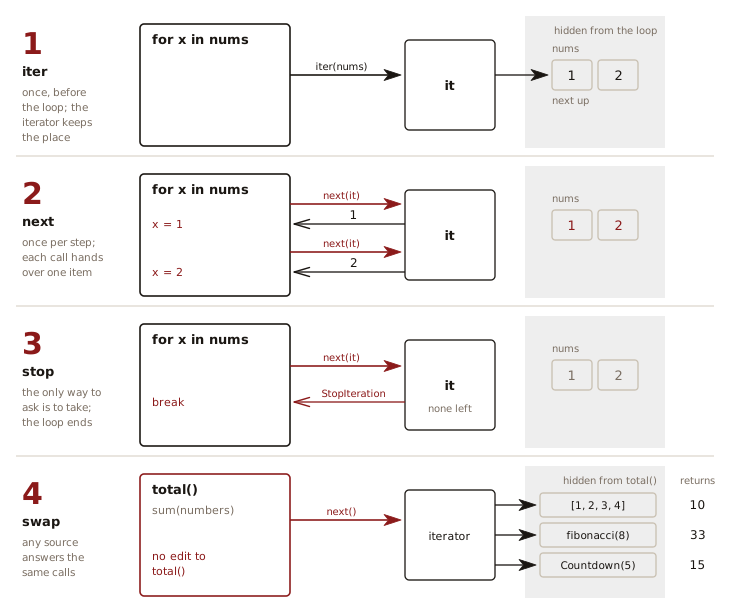
The shaded region in each frame holds what the caller cannot
see. Inside total(), sum() makes the
same iter() and next() calls as the
written-out for loop, so a new source needs no
change to total(). The third frame shows a limit of
the protocol. A caller learns that the items have run out by
asking for one more.
fibonacci(8) returns an iterator, which one pass
exhausts. Countdown(5) is an iterable whose
__iter__() builds a fresh generator for every pass,
so you can iterate over it repeatedly.
The test file confirms that:
fibonacci()produces the expected sequence, including the empty and one-item cases.Countdowncounts down to 1, andCountdown(0)produces nothing.- A
Countdownproduces the same values on a second pass. total()sums a list, a generator, and aCountdown.
# test_iterators.py
import pytest
from iterators import Countdown, fibonacci, total

@pytest.mark.parametrize("n, expected", [
    (8, [0, 1, 1, 2, 3, 5, 8, 13]),
    (0, []),
    (1, [0]),
])
def test_fibonacci_sequence(
    n: int, expected: list[int]
) -> None:
    assert list(fibonacci(n)) == expected

def test_countdown_sequence() -> None:
    assert list(Countdown(5)) == [5, 4, 3, 2, 1]
    assert list(Countdown(0)) == []

def test_countdown_is_reiterable() -> None:
    c = Countdown(3)
    assert list(c) == [3, 2, 1]
    assert iter(c) is not iter(c)
    assert list(c) == [3, 2, 1]

def test_total_over_any_iterable() -> None:
    assert total([1, 2, 3, 4]) == 10
    assert total(fibonacci(8)) == 33
    assert total(Countdown(5)) == 15
Generators are lazy. fibonacci(1_000_000)
computes nothing until you iterate over it, and produces one
value at a time, so it works on streams too large to hold in
memory. generator_memory.py
compares the generator’s memory with a list holding the same
values. Its squares() returns a generator
expression, the one-line form of a generator:
# generator_memory.py
import tracemalloc
from collections.abc import Iterator
from typing import Final
from benchmark import report

def squares(n: int) -> Iterator[int]:
    return (i * i for i in range(n))

N: Final[int] = 1_000_000

tracemalloc.start()
total = 0
for x in squares(N):
    total += x
_, lazy_peak = tracemalloc.get_traced_memory()
tracemalloc.stop()

tracemalloc.start()
collected = list(squares(N))
_, eager_peak = tracemalloc.get_traced_memory()
tracemalloc.stop()

report(lazy_bytes=lazy_peak, eager_bytes=eager_peak)
print(f"generator used far less memory: "
      f"{lazy_peak < eager_peak * 0.01}")
#: generator used far less memory: True
Iterating over the generator keeps one squared value alive at a time. Collecting the same million values into a list keeps all of them alive at once, so the generator’s peak stays under one percent of the list’s.
A generator can be infinite. A
while True loop that yields forever, or
itertools.count(), produces values on demand with
no end. You take as many as you need (itertools.islice()
does the taking), while a list must hold every value first.
The Costs of Laziness
Laziness has two surprising consequences, and both are silent:
# generator_lifecycle.py
from collections.abc import Iterator

def squares(n: int) -> Iterator[int]:
    print("first next() reached the body")
    for i in range(n):
        yield i * i

sq = squares(6)  # Body not executed
print("created")
#: created
print(next(sq))
#: first next() reached the body
#: 0
print(list(sq))  # The values that are left
#: [1, 4, 9, 16, 25]
print(list(sq))  # Exhausted: empty, and no error
#: []
The Body Waits for
the First next()
Calling squares(6) runs none of its body. The
print() at the top runs only when something demands
the first value. It runs once, not on every value. Each later
next() resumes the body just after the
yield instead of restarting it.
Any validation at the top of a generator inherits this delay.
A check meant to reject a bad argument raises its exception at
the first next(), far from the call that caused the
problem.
To validate eagerly, check the arguments in a plain function and have it return an inner generator:
# eager_validation.py
from collections.abc import Iterator
from exceptions import expect

def squares(n: int) -> Iterator[int]:
    if n < 0:
        raise ValueError(f"n must not be negative: {n}")
    def produce() -> Iterator[int]:
        for i in range(n):
            yield i * i
    return produce()

# The check runs now, not at first next():
expect(ValueError, squares, -1)
#: [ValueError] n must not be negative: -1
squares() has no yield, so calling
it runs the check immediately. Only produce()
waits.
An Exhausted Generator Is Silently Empty
The second surprise in generator_lifecycle.py is
its second call to list(sq). An exhausted generator
produces nothing and raises nothing, so the empty
list(sq) leaves no error to point at the bug.
When you must walk data twice, collect it into a list once,
or hand out an iterable like Countdown in iterators.py, whose
__iter__() builds a fresh generator for every
pass.
Laziness and single use are separate properties.
Countdown is as lazy as the generator its
__iter__() builds, yet it survives repeated passes,
because each pass gets a fresh iterator. range()
works the same way. One range object can drive loop
after loop. The iterator runs out, not the iterable that made
it.
An Iterable[T] annotation gives no warning,
because it describes a list and a half-spent generator equally
well. A function that walks its argument twice therefore
type-checks and then returns a wrong answer on the second
pass:
# walked_twice.py
from collections.abc import Collection, Iterable, Iterator

def gen(n: int) -> Iterator[int]:
    yield from range(n)

def twice_iterable(xs: Iterable[int]) -> tuple[int, int]:
    return sum(xs), sum(xs)

def twice_collection(
    xs: Collection[int]
) -> tuple[int, int]:
    return sum(xs), sum(xs)

# Type checker sees nothing wrong
print(twice_iterable(gen(3)))
#: (3, 0)
# The same values, in a list
print(twice_collection([0, 1, 2]))
#: (3, 3)
When a function iterates over its argument more than once,
say so in the signature. Collection[T] and
Sequence[T] also require __len__(),
which no generator has, so the type checker rejects the
generator at the call instead of letting it run wrong.
twice_collection(gen(3)) is the call the checker
refuses, and that is why the listing leaves it out. Every
chapter listing must type-check. total() in iterators.py stays
Iterable[int] because it sums once.
What tee() Buffers
itertools.tee(it, 2) splits one iterator into
two independent ones. That looks like a third way to walk data
twice, and it rarely saves memory over collecting a list. The
squares() below is the plain-function form from eager_validation.py, with
the generator expression standing in for
produce():
# tee.py
import tracemalloc
from collections.abc import Iterator
from itertools import tee
from typing import Final
from benchmark import report

def squares(n: int) -> Iterator[int]:
    return (i * i for i in range(n))

# Two independent readers, one source
a, b = tee(squares(5))
print(list(a), list(b))
#: [0, 1, 4, 9, 16] [0, 1, 4, 9, 16]

N: Final[int] = 100_000
first, second = tee(squares(N))
tracemalloc.start()
for _ in first:  # Drain one branch; second has not started
    pass
buffered, _ = tracemalloc.get_traced_memory()
tracemalloc.stop()

tracemalloc.start()
collected = list(squares(N))
listed, _ = tracemalloc.get_traced_memory()
tracemalloc.stop()
report(tee_bytes=buffered, list_bytes=listed)
print(f"tee held as much as the list: "
      f"{buffered > listed * 0.9}")
#: tee held as much as the list: True

# Same N, but both branches advance together:
first2, second2 = tee(squares(N))
tracemalloc.start()
for x, y in zip(first2, second2,
                strict=True):
    pass
_, lockstep = tracemalloc.get_traced_memory()
tracemalloc.stop()
report(lockstep_bytes=lockstep)
print(f"lockstep buffered far less: "
      f"{lockstep < listed * 0.1}")
#: lockstep buffered far less: True
Both branches see all five squares, so tee()
delivers the second pass the generator could not.
tee() buffers every item the leading branch
consumes until the trailing one catches up, so when
first drains while second waits, the
buffer holds the whole stream. That is the memory a list uses,
and the comparison confirms it (one machine measured 4,096,992
bytes buffered against 3,999,992 for the list). The last block
advances first2 and second2 together
instead, one zip() step at a time, so
tee() buffers at most the gap between them. That
gap stays near zero, and the measurement confirms it. Use
tee() when two consumers advance together, not when
one finishes before the other starts.
tee() is also single-threaded. Its branches
share one buffer with no lock, so two threads advancing them at
the same time can raise a RuntimeError. Concurrency
covers threading.concurrent_tee(), the thread-safe
version, along with what goes wrong when two threads call
next() on the same iterator.
Delegating with
yield from
A generator can delegate part of its work to another iterator
using yield from. yield from yields
every value that iterator produces, in turn, as if the outer
generator had written the loop:
# yield_from.py
from collections.abc import Iterator, Sequence

type Nested = int | Sequence[Nested]

def flatten_loop(nested: Sequence[Nested]) -> Iterator[int]:
    for item in nested:
        if isinstance(item, int):
            yield item
        else:
            # Spelled out
            for x in flatten_loop(item):  # noqa: UP028
                yield x

def flatten(nested: Sequence[Nested]) -> Iterator[int]:
    for item in nested:
        if isinstance(item, int):
            yield item
        else:
            # The same loop, delegated
            yield from flatten(item)

data: Sequence[Nested] = [1, [2, 3], [4, [5, 6]], 7]
print(list(flatten_loop(data)))
#: [1, 2, 3, 4, 5, 6, 7]
print(list(flatten(data)))
#: [1, 2, 3, 4, 5, 6, 7]
Both functions call themselves on each nested sequence, and
both pass each value from the recursive call out to the caller.
flatten_loop() passes the values out by hand. It
starts the recursive call, then re-yields each value that call
produces. flatten() replaces those two lines with
yield from, and the matching output shows the
substitution is exact.
flatten_loop() carries a # noqa
because ruff’s UP028 rule reports a
for loop whose body is a lone yield of
the loop variable, and tells you to write
yield from instead.
The two forms agree for a generator that yields values and
returns None, as flatten() does. The
yield from expression, however, has a value.
result = yield from inner() binds whatever
inner() returned when it stopped. The hand-written
loop drops that value. yield from also forwards
send() and throw() into the inner
generator, and the hand-written loop has no way to forward them.
Generators
uses all three channels: the yielded values, the return value,
and send().
test_flatten() runs flatten() and
flatten_loop() over the same inputs and expects the
same flat list from each:
# test_yield_from.py
from collections.abc import Callable, Iterator, Sequence
import pytest
from yield_from import Nested, flatten, flatten_loop

type Flattener = Callable[[Sequence[Nested]], Iterator[int]]

@pytest.mark.parametrize("flatten_with",
                         [flatten, flatten_loop])
@pytest.mark.parametrize("nested, expected", [
    ([1, [2, 3], [4, [5, 6]], 7], [1, 2, 3, 4, 5, 6, 7]),
    ([1, 2, 3], [1, 2, 3]),
])
def test_flatten(
    flatten_with: Flattener,
    nested: Sequence[Nested], expected: list[int]
) -> None:
    assert list(flatten_with(nested)) == expected
Reusable Algorithms
The standard library’s itertools module contains
the generic iterator algorithms chain(),
islice(), groupby(),
takewhile(), and more. Each of these consumes and
produces iterators. Combine them with generator
expressions such as
(x * x for x in data if x > 0) to build
pipelines that stay lazy end to end. Each stage pulls one item
at a time, so an infinite source is fine as long as something
downstream stops it:
# reusable_algorithms.py
from itertools import count, islice, takewhile

numbers = count(1)  # Infinite: 1, 2, 3, ...
# The generator expression squares the odd numbers, lazily:
odd_squares = (n * n for n in numbers if n % 2)
print(list(islice(odd_squares, 5)))  # Take the first five
#: [1, 9, 25, 49, 81]

# takewhile() stops when its condition fails:
print(list(takewhile(lambda s: s < 50,
                     (n * n for n in count(1)))))
#: [1, 4, 9, 16, 25, 36, 49]
Nothing runs until list() pulls the values.
islice() and takewhile() decide when
to stop, so the infinite count(1) produces no more
than they pull.
islice() is also how you slice an iterator. A
generator defines no __getitem__(), so the list
habit odd_squares[:5] raises a
TypeError instead. Functional
Toolkits covers chain() and
groupby() in full, including the sorted-input trap
groupby() sets for an unwary caller.
Choose takewhile() deliberately, because its
lookalike is the if clause of a generator
expression (or filter()), and these behave
differently with an infinite source. The if version
skips nonmatching values but keeps looking, so once values stop
matching, a list() around it runs forever.
takewhile() stops at the first failure. Skipping
and stopping look the same on finite data and behave nothing
alike on infinite data.
A test can demonstrate that difference, but not by writing
list(count(1)). That call runs forever, and so does
the test. In test_endless.py,
counter() stands in for count(1). It
counts up the same way, then raises an exception once something
has pulled LIMIT values:
# test_endless.py
from collections.abc import Iterator
from itertools import count, islice, takewhile
from typing import Final
import pytest

LIMIT: Final[int] = 1000

class Tripwire(Exception):
    pass

def counter(limit: int) -> Iterator[int]:
    for n in count(1):
        if n > limit:
            raise Tripwire(
                f"pulled {limit} values and kept asking")
        yield n

def test_list_keeps_pulling_from_an_infinite_source(
) -> None:
    with pytest.raises(Tripwire):
        list(counter(LIMIT))

def test_the_if_clause_skips_but_never_stops() -> None:
    small = (n for n in counter(LIMIT) if n < 3)
    with pytest.raises(Tripwire):
        list(small)

def test_takewhile_stops_at_the_first_failure() -> None:
    assert list(takewhile(lambda n: n < 3,
                          counter(LIMIT))) == [1, 2]

def test_islice_stops_after_its_count() -> None:
    assert list(islice(counter(LIMIT), 3)) == [1, 2, 3]
test_list_keeps_pulling_from_an_infinite_source()
is list(count(1)) with a stopping point built into
the source. In
test_the_if_clause_skips_but_never_stops(), nothing
after 2 satisfies n < 3, yet the
generator expression keeps pulling from counter()
to find another match, and trips the same wire. The
takewhile() and islice() tests stop on
their own, before reaching the tripwire.
Failing at 1,000 values stands in for how a real program fails. A real program stops responding, or it dies when it exhausts memory.
The toolchain lets list(count(1)) through. The
type checker accepts it, and so does ruff with
every one of its rules enabled. No type checker can read the
code and decide whether an iterator ever ends. A generator built
from while True looks the same as a finite one
until it runs. The one rule that touches this code is a
comprehension check. It offers to rewrite
[n for n in count(1)] as
list(count(1)), the same problem with fewer
characters.
A Type-Checking Iterator
The Decorator Pattern wraps an existing iterator, producing a new one with the same interface and added behavior. Here, the wrapper forces every item to match an expected type:
# typed_iterator.py
from collections.abc import Iterator
from dataclasses import dataclass
from typing import override

@dataclass(eq=False)
class TypedIterator[T](Iterator[T]):
    imp: Iterator[object]
    expected: type[T]
    accepted: int = 0  # State a generator cannot expose

    @override
    def __next__(self) -> T:
        obj = next(self.imp)
        if not isinstance(obj, self.expected):
            raise TypeError(
                f"TypedIterator for {self.expected} "
                f"encountered {type(obj).__name__}")
        self.accepted += 1
        return obj

if __name__ == "__main__":
    checked = TypedIterator(iter([1, 2, 3]), int)
    print(next(checked), next(checked))
    print(checked.accepted)  # Read mid-stream
#: 1 2
#: 2
collections.abc.Iterator supplies
__iter__() to its subclasses, so
TypedIterator defines __next__() and
inherits __iter__().
The dataclass decoration carries
eq=False. A data class that generates
__eq__() sets __hash__ to
None, so the wrapper can no longer go in a set or
serve as a dict key, as every other iterator can. Field-by-field
comparison is also the wrong question to ask about a cursor. Two
wrappers over one source compare equal as soon as their counts
agree, though each has delivered different items, and two
wrappers over separate iterators of the same list compare
unequal. Turning equality off restores the identity comparison
an iterator should have.
A generator wraps an iterator just as well, and in fewer lines:
# typed_generator.py
from collections.abc import Iterable, Iterator

def typed[T](
    it: Iterable[object], expected: type[T]
) -> Iterator[T]:
    for obj in it:
        if not isinstance(obj, expected):
            raise TypeError(
                f"expected {expected}, "
                f"got {type(obj).__name__}")
        yield obj

if __name__ == "__main__":
    print(list(typed([1, 2, 3], int)))
#: [1, 2, 3]
Use the class when the wrapper needs its own state or extra
methods, such as accepted in typed_iterator.py. A
caller reads accepted mid-stream, while a
generator’s local variables have no name a caller can use. Use
the generator when it does not. Either way, the wrapper plugs
into every place that accepts an iterator, because every such
place uses the same protocol. The two wrappers’ inputs differ,
though. typed() takes an
Iterable[object], so a list is fine.
TypedIterator calls next() on what it
stores, so it needs an Iterator[object]. Write
TypedIterator(iter(items), int), not
TypedIterator(items, int). The type checker rejects
the second form. Both take expected: type[T], so
the type checker carries the element type through.
typed(items, int) is an Iterator[int],
not an Iterator[Any].
Each test passes a list of int through one
wrapper and gets it back unchanged, then expects a
TypeError once a str appears:
# test_typed.py
import pytest
from typed_generator import typed
from typed_iterator import TypedIterator

def test_typed_generator_passes_and_rejects() -> None:
    assert list(typed([1, 2, 3], int)) == [1, 2, 3]
    with pytest.raises(TypeError):
        list(typed([1, "two", 3], int))

def test_typed_iterator_passes_and_rejects() -> None:
    assert list(TypedIterator(iter([1, 2, 3]),
                              int)) == [1, 2, 3]
    with pytest.raises(TypeError):
        list(TypedIterator(iter([1, "two", 3]), int))
The Pattern That Disappeared
GoF Design Patterns gives Iterator a class
of its own, with separate methods to start a traversal, advance
it, test whether it has finished, and read the current item. It
names them First(), Next(),
IsDone(), and CurrentItem(). Nothing
in this chapter looks like that. Those four methods dissolved
into two: __iter__() and __next__().
The language calls both on your behalf.
first()
and current_item() Rebuild the List
Written in Python, the four GoF Iterator methods
show what first() and current_item()
ask of a source. The listing names GoF’s Next()
advance(), so a reader cannot confuse
advance() with Python’s next(). Over a
list the four are unremarkable. first() resets an
index, is_done() compares it to len(),
and current_item() reads without consuming. Over a
generator, you can still write all four, but only by keeping
everything the traversal has seen:
# gof_iterator.py
from collections.abc import Iterable, Iterator
from typing import Protocol

DONE = sentinel("DONE")

class GoFIterator[T](Protocol):
    def first(self) -> None: ...
    def advance(self) -> None: ...
    def is_done(self) -> bool: ...
    def current_item(self) -> T: ...

class OverStream[T]:
    def __init__(self, source: Iterable[T]) -> None:
        self.source: Iterator[T] = iter(source)
        # Every item the traversal has read
        self.seen: list[T] = []
        self.index = 0

    def first(self) -> None:
        self.index = 0  # Rewinds into seen, not into source

    def advance(self) -> None:
        self.index += 1

    def is_done(self) -> bool:
        while len(self.seen) <= self.index:
            item = next(self.source, DONE)
            if item is DONE:
                return True
            self.seen.append(item)
        return False

    def current_item(self) -> T:
        return self.seen[self.index]

def traverse(it: GoFIterator[int]) -> list[int]:
    out: list[int] = []
    while not it.is_done():
        out.append(it.current_item())
        it.advance()
    return out

stream = OverStream(x * 2 for x in [1, 2, 3])
print(traverse(stream))
#: [2, 4, 6]
stream.first()
# A second pass, from a spent generator
print(traverse(stream))
#: [2, 4, 6]
print(stream.seen)
#: [2, 4, 6]
traverse() is the loop a GoF caller writes, and
it drives any type with those four methods, because
GoFIterator is a protocol
rather than a base class. The first pass spends the generator,
yet first() rewinds and traverse()
produces the same three values.
seen is how. is_done() pulls from
the source when the cache falls short of the current index, and
keeps every item it reads. current_item() then
indexes the cache instead of touching the source, so it reports
a value without advancing. The last line of output shows that by
the time all four methods work, seen holds the
entire stream. The interface needs more than a buffer. It
rebuilds the list.
Rebuilding the list is the cost the pattern hides.
first() and current_item() assume a
collection you can re-read and inspect in place, so honoring
them over a stream means recreating one, item by item. The
chapter has now reached that conclusion three times: here, in
tee()’s buffering, and in the advice to collect
into a list when you must walk data twice. Python dropped both
methods rather than paying for them everywhere. Without them,
advance() must return the value it reached. That
method is __next__().
Asking Consumes an Item
A GoF iterator answers whether it has finished as often as
you ask, without advancing. Python makes that question part of
__next__(), so the only way to ask is to take. The
answer arrives as a StopIteration exception that
the for loop swallows on your behalf. You can catch
that exception yourself, or hand next() a default
and compare against it, but neither restores the free query of
the GoF Iterator:
# asking_costs.py
from collections.abc import Iterator
from exceptions import expect

DONE = sentinel("DONE")

def doubled(source: Iterator[int]) -> Iterator[int]:
    # The exception escapes when the source runs out:
    while True:
        yield next(source) * 2

def doubled_ok(source: Iterator[int]) -> Iterator[int]:
    for n in source:  # The loop absorbs the exception
        yield n * 2

numbers = iter([1, 2])
print(next(numbers, DONE) is DONE)  # Asking consumes the 1
#: False
print(next(numbers, DONE) is DONE)  # Asking consumes the 2
#: False
print(next(numbers, DONE) is DONE)  # No more left
#: True
letters = iter("abcd")
# A membership test consumes too:
print("c" in letters, list(letters))
#: True ['d']

expect(RuntimeError, list, doubled(iter([1, 2])))
#: [RuntimeError] generator raised StopIteration
print(list(doubled_ok(iter([1, 2]))))
#: [2, 4]
Each question costs an item. Nothing in the protocol looks
ahead without advancing. That is why a peekable iterator must
buffer, and why tee() buffered a whole stream in tee.py. A membership test
pays the same way. "c" in letters pulls items until
it finds a match, and every item it pulled is gone, the match
included.
DONE is a sentinel,
because the answer must differ from every value the source could
yield. None collapses an exhausted source and a
source that yields None into the same reply. The
built-in iter() uses a sentinel the same way in its
two-argument form. iter(callable, DONE) calls
callable until it hands back DONE.
A StopIteration that escapes a generator body
becomes a RuntimeError (PEP 479), so an
ordinary end of stream reads like a bug somewhere else. Only a
bare next() hands you a StopIteration.
With a default, next() returns the default, and
every other construct here absorbs the exception.
yield from source stops delegating when the source
runs out. It passes each value through unchanged, though, so
per-item work such as doubling needs a loop. That is why
doubled_ok() uses for, and the loop
absorbs the exception as every for loop in this
chapter does. The fix is rarely a try. Let the loop
do the asking.
The Protocol Answers Nothing
Both surprises in The Costs
of Laziness come from the same rule. The only way to find
out whether the body accepts its arguments is to pull a value
and let it run, and the only way to find out whether the source
has run out is to pull and get nothing back. for
and list() catch that second answer and report
nothing, so an exhausted source and an empty one produce
identical output. The protocol buffers nothing and tells you
nothing in advance. Every tool in this chapter that does answer
in advance, tee(), OverStream, or a
peekable wrapper, pays for the answer with a buffer.
Exercises
This chapter’s solutions give a hint, usually the shape of the code, and a full answer for each exercise.
- Write a generator
evens(n)that yields the firstneven numbers, and confirmtotal()fromiterators.pysums them without modification. - Rewrite
Countdownto also supportlen(), then explain why a generator cannot. - Use
itertools.islice()to take the first 10 values offibonacci(1_000_000)without computing the rest. generator_lifecycle.pyreturns an empty list on its second pass. Fix the caller two ways: collect into a list once and reuse it, then instead convertsquares()into aCountdown-style iterable class whose__iter__()builds a fresh generator. Which fix would you choose for a stream of a million items, and why?tee.pymeasures two extremes: one branch drained before the other starts, and both branches in lockstep. Measure what lies between them. Advance one branchkitems ahead of the other, then walk both together so the leading branch stayskitems ahead. Predict how the buffer grows withkbefore you measure it, then measure it for two values ofkwithtee.py’stracemallocapproach, and explain the result using the rule in Whattee()Buffers.- The prose pairs the generator expression’s
ifclause withfilter(), but no test coversfilter(). Add one totest_endless.py, and say which existing test it should resemble. gof_iterator.pyshows only the stream version. WriteOverSequenceover aSequence[T], confirmtraverse()drives it with no changes totraverse(), and explain why it needs noseenlist. Then build anOverStreamoveritertools.count(1).traverse()runs forever on an infinite source, so drive the four methods yourself for 50,000 steps and reportlen(stream.seen). What hasfirst()cost you on an infinite source?- Write
peek(it)that reports an iterator’s next value without consuming it. You cannot, so write aPeekablewrapper that can, and name what it stores that a bare iterator does not. flatten()recurses on anything that is not anint. Call it on[1, "ab", 2]and explain theRecursionErroryou get, given that a one-character string is still aSequence. Then fixflatten()so astryields as one item, and say what the same fix looks like inflatten_loop().typed()raises aTypeErroron the first item of the wrong type, which ends the stream. Writetyped_skipping(), which drops mismatched items and keeps going, then say which of the two you would want wrapping a parsed log file, and why. Which one is easier to write asTypedIterator?