Composite and Interpreter

An item can hold more items of its own kind, and code must treat one item and a whole group the same way. Composite builds that tree, and Interpreter reads one as a sentence and evaluates it.
In Composite, each node is a leaf or a group of
nodes, and one call serves both. In Interpreter, the
tree is a sentence in a small language, and evaluating the
sentence walks the tree. GoF Design Patterns presents
them as separate patterns, but Interpreter is
Composite with meaning attached. In Python both reduce
to one technique: a union of records for the nodes, and
recursive functions that match on them. Each of
those match statements is exhaustive,
so the type checker reports a node kind that no case
handles.
The Classic Composite
A file system is the canonical composite. A directory holds entries, and each entry is a file or another directory. The point is uniformity. One call serves a file, a directory, and the whole tree.
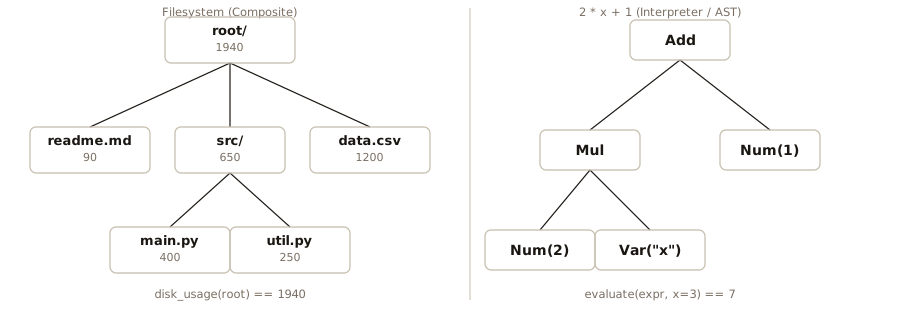
disk_usage(root) adds up every file below
root to get 1940, and the same call on
src or on a single file answers for that subtree or
file.
The traditional version puts each operation inside the node classes, under an abstract method on a shared base:
# filesystem_classic.py
from abc import ABC, abstractmethod
from collections.abc import Iterator
from typing import override
from record import record

class Node(ABC):
    __slots__ = ()
    name: str

    @abstractmethod
    def disk_usage(self) -> int: ...

    @abstractmethod
    def walk(self, prefix: str = "") -> Iterator[str]: ...

@record
class File(Node):
    name: str
    size: int

    @override
    def disk_usage(self) -> int:
        return self.size

    @override
    def walk(self, prefix: str = "") -> Iterator[str]:
        yield prefix + self.name

@record
class Directory(Node):
    name: str
    entries: tuple[Node, ...]

    @override
    def disk_usage(self) -> int:
        return sum(e.disk_usage() for e in self.entries)

    @override
    def walk(self, prefix: str = "") -> Iterator[str]:
        for e in self.entries:
            yield from e.walk(f"{prefix}{self.name}/")

src = Directory("src", (
    File("main.py", 400), File("util.py", 250)))
root = Directory("root", (
    File("readme.md", 90), src, File("data.csv", 1200)))
print(root.disk_usage(), src.disk_usage(),
      File("lone.txt", 10).disk_usage())
#: 1940 650 10
for path in root.walk():
    print(path)
#: root/readme.md
#: root/src/main.py
#: root/src/util.py
#: root/data.csv
Directory.disk_usage() calls
disk_usage() on each entry without testing whether
the entry is a File or another
Directory. The demo’s first print()
makes that one call on the whole tree, on the src
subtree, and on a lone file.
Adding a node type is one class. A plugin writes it and edits
nothing above it. Adding an operation exposes the weakness.
walk() needs a method in every class, and counting
files or finding an entry by name each needs another. Visitor exists to
solve this problem.
A Composite of Data Classes
The next version moves the operations out of the classes. The nodes keep their fields, a union names the closed set of alternatives, and each operation becomes a recursive function that matches on that union. The nodes stay records, now with no base class above them:
# filesystem.py
from collections.abc import Iterator
from typing import assert_never
from record import record

@record
class File:
    name: str
    size: int

@record
class Directory:
    name: str
    entries: tuple[Node, ...]

type Node = File | Directory

def disk_usage(entry: Node) -> int:
    match entry:
        case File(_, size):
            return size
        case Directory(_, entries):
            return sum(disk_usage(e) for e in entries)
        case _:
            assert_never(entry)

def walk(entry: Node, prefix: str = "") -> Iterator[str]:
    match entry:
        case File(name, _):
            yield prefix + name
        case Directory(name, entries):
            for e in entries:
                yield from walk(e, f"{prefix}{name}/")
        case _:
            assert_never(entry)

if __name__ == "__main__":
    src = Directory("src", (
        File("main.py", 400), File("util.py", 250)))
    root = Directory("root", (
        File("readme.md", 90), src, File("data.csv", 1200)))
    print(disk_usage(root), disk_usage(src),
          disk_usage(File("lone.txt", 10)))
    for path in walk(root):
        print(path)
#: 1940 650 10
#: root/readme.md
#: root/src/main.py
#: root/src/util.py
#: root/data.csv
Node is a recursive union.
Directory holds a tuple[Node, ...], so
the alias names itself through one of its own members, and that
self-reference makes the tree a tree.
Directory mentions Node above the
type
statement that defines Node. That works because
Python evaluates annotations and type aliases
lazily, the deferred
evaluation. The alias can therefore sit below the classes it
unites, where it reads as a summary of them rather than as a
forward declaration.
Every function over Node repeats the union’s
recursion. Directory contains Nodes,
so disk_usage() and walk() call
themselves on each entry. Each match needs one case
per member of the union.
disk_usage() still accepts a lone
File, a subtree, or the whole tree. What differs
from filesystem_classic.py is
only where the operations live. disk_usage() and
walk() are ordinary functions outside the node
classes, so a new operation is a new function, and the nodes
stay unchanged. In the classic version a new node type is one
class and a new operation is a method in every class. The
pairing has a name: the expression
problem. Rethinking
Objects works out the same split with shapes, including the
assert_never() in each case _. If you
add a Symlink to the Node union, every
function whose case _ calls
assert_never() fails type checking until it handles
Symlink (see exercise 2).
walk() is a generator, so traversing a composite
is lazy. The yield from
flattens the recursion into a single stream of paths, and any
consumer of that stream stays decoupled from the tree
structure.
The entries field is a tuple of
Node, so the whole tree is immutable. A
list there would leave the tree mutable. A record
freezes the binding of the field, and the list it holds keeps
its append(), as Rethinking
Objects demonstrates. With the tuple, sharing a subtree is
safe. The demo builds src first, then places it
inside root, and src stays as
built.
The tests check that disk_usage() answers for
the whole tree, a subtree, and a lone file, that
walk() yields each file’s full path, and that an
empty directory has size 0 and yields no paths:
# test_filesystem.py
from typing import Final
import pytest
from filesystem import (Directory, File, Node,
                        disk_usage, walk)

SUB: Final[Directory] = Directory(
    "sub", (File("b", 2), File("c", 3)))
TREE: Final[Directory] = Directory(
    "top", (File("a", 1), SUB))

@pytest.mark.parametrize("entry, expected", [
    (TREE, 6),
    (SUB, 5),
    (File("solo", 7), 7),
])
def test_disk_usage_is_uniform(entry: Node,
                               expected: int) -> None:
    assert disk_usage(entry) == expected

def test_walk_yields_full_paths() -> None:
    assert list(walk(TREE)) == [
        "top/a", "top/sub/b", "top/sub/c"]

def test_empty_directory() -> None:
    assert disk_usage(Directory("empty", ())) == 0
    assert list(walk(Directory("empty", ()))) == []
The classic version wins when the set of node types is open.
If plugins or other packages must add new kinds of entries, a
method on a base class lets them do that in their own code, but
a central match needs an edit in yours. The guidance
on when not to match applies to node types.
A file and a directory are both a Path, which
makes pathlib look like a Composite.
pathlib has the uniform interface.
name, exists(), and
stat() work on either kind of entry, and
iterdir() and rglob() walk the tree
without asking which kind they hold. pathlib lacks
the structure. A Path is an immutable value that
names a location and holds no entries. The tree lives in the
operating system’s filesystem, and iterdir() asks
the OS for the children each time you call it. No
Path method adds up a result over that tree the way
disk_usage() does. On a directory,
stat().st_size reports the size of the directory
entry rather than the size of its contents, so the recursion
falls to you:
total = sum(p.stat().st_size for p in root.rglob("*")
            if p.is_file())
rglob() supplies the traversal, and
sum() supplies the combining step that
disk_usage() performs for a Directory.
The filesystem is the composite, and a Path is a
handle into it.
Interpreter
A tree whose shape follows a grammar is an abstract
syntax tree (AST). Python’s own compiler builds one of
these for every source file. ast.parse() returns it
to you as node objects, and ast.NodeVisitor walks
them in the style of Visitor.
Interpreter is Composite applied to language. Representing each construct as a node type turns evaluation into a tree walk.
In most languages the pattern needs a class per construct and a parser to build the trees. Python shrinks the classes and removes the parser, for one specific case: sentences written as Python source in which every operator has at least one node operand. A record declares a node in three or four lines, and operator overloading lets Python’s own parser build the trees. A GoF Interpreter more often parses a rules file, a configuration value, or a query a user types at runtime. Those arrive as text, and text needs a real parser. Here is the complete grammar for a small arithmetic language:
# expr.py
from record import record

class Operators:
    __slots__ = ()

    def __add__(self: Expr, other: Expr | int) -> Add:
        return Add(self, wrap(other))

    def __radd__(self: Expr, other: int) -> Add:
        return Add(Num(other), self)

    def __mul__(self: Expr, other: Expr | int) -> Mul:
        return Mul(self, wrap(other))

    def __rmul__(self: Expr, other: int) -> Mul:
        return Mul(Num(other), self)

@record
class Num(Operators):
    value: int

@record
class Var(Operators):
    name: str

@record
class Add(Operators):
    left: Expr
    right: Expr

@record
class Mul(Operators):
    left: Expr
    right: Expr

type Expr = Num | Var | Add | Mul

def wrap(value: Expr | int) -> Expr:
    return Num(value) if isinstance(value, int) else value
The Nodes and the
Operators Base
The four node classes are the grammar. An expression is a
number, a variable, a sum, or a product. Add and
Mul hold other expressions, so the tree is a
composite.
Operators is a base class but not a member of
Expr, and the split is on purpose. Every node
shares the operator methods, so those live on a base and each
node inherits them. Each node means something different, so
meaning lives in the walkers. Each walker’s
assert_never() needs the union to verify that its
match covers every member. Expr is the
contract. A base class is an open set that any new subclass
silently joins, so if you annotate evaluate() with
Operators instead, assert_never()
fails type checking even with a case for every node.
Operators That Build Nodes
Every node inherits __add__() and
__mul__(), and those methods compute nothing. They
build nodes. Annotating self as Expr
lets Add(self, ...) type-check. An implicit
self means “some subclass of
Operators,” and the Expr annotation
declares to the type checker that self is a member
of the union.
ty accepts a self annotation
narrower than the class. Pyright and mypy require the declared
type of self to be a supertype of its class, so
under either of them the portable form leaves self
implicit and writes cast(Expr, self) at each
construction.
Writing x + 1 produces an Add, so
ordinary Python arithmetic notation constructs the AST. The
reflected forms __radd__() and
__rmul__() handle an integer on the left, and
wrap() promotes an integer on the right to a
Num node. 2 * x + 1 is therefore a
valid sentence in the little language. Python has parsed it,
applying its precedence rules, before the interpreter runs.
The reflected methods depend on the operator dispatch from Multiple
Dispatching. 2 * x works because
int.__mul__() returns NotImplemented
and Python turns to x.__rmul__(2). Unlike that
chapter’s Meters, though, these reflected methods
accept any operand. ty reports "a" + x
as unsupported-operator in source it checks, but at
runtime Var.__radd__() runs before str
tries to concatenate, and the result is
Add(Num("a"), x), an ill-typed tree whose error
waits for evaluate() to add the "a".
If each operator method returns NotImplemented for
an operand it cannot use, "a" + x raises a
TypeError at the + (see exercise
6).
SymPy expressions, Polars column arithmetic, and SQLAlchemy filter conditions all use this technique. Overloaded operators build an expression tree, and a library interprets that tree later, symbolically, over a whole column, or as SQL.
Python’s grammar sets the limit of the technique. You can
overload the arithmetic, bitwise, and comparison operators this
way, so an expression written with them builds nodes instead of
computing. ==, though, compares nodes instead of
building one. @record writes its own
__eq__() onto every node class. Attribute lookup
finds a class’s own method before an inherited one, so that
generated __eq__() shadows anything
Operators defines.
expr.py leaves
== alone. The nodes compare by value, and evaluate.py’s demo and its
tests rely on that comparison. When a library’s ==
must build a node, as SQLAlchemy’s col == 5 does,
the library sets eq=False on the dataclass, giving
up structural comparison, and writes its own
__eq__(). This chapter keeps structural comparison.
A class gets either that or an == that builds a
node, not both.
and, or, and not
belong to Python alone. Python tests the operand’s truth value.
Then and and or return one of the two
objects, and not returns a bool.
x and y evaluates to y, builds
nothing, and reports no error. An expression language that needs
boolean operators overloads & and
| instead, so a Pandas filter reads
(a > 1) & (b > 2). The parentheses change
the parse. & binds tighter than
>, so bare a > 1 & b > 2
parses 1 & b first.
Evaluation Is a Tree Walk
Evaluation is a recursive match function.
Variables need values, which the caller supplies as keyword
arguments:
# evaluate.py
from typing import assert_never
from expr import Add, Expr, Mul, Num, Var

def evaluate(e: Expr, /, **env: int) -> int:
    match e:
        case Num(value):
            return value
        case Var(name):
            return env[name]
        case Add(left, right):
            return (evaluate(left, **env)
                    + evaluate(right, **env))
        case Mul(left, right):
            return (evaluate(left, **env)
                    * evaluate(right, **env))
        case _:
            assert_never(e)

if __name__ == "__main__":
    x = Var("x")
    expr = 2 * x + 1
    by_hand = Add(Mul(Num(2), x), Num(1))
    print(expr == by_hand, expr.left)
    print(evaluate(expr, x=3), evaluate(expr, x=10))  # [1]
#: True Mul(left=Num(value=2), right=Var(name='x'))
#: 7 21
The demo confirms that the operators build the tree you
assemble by hand. Records generate __eq__(), so
expr == by_hand compares the two trees by value.
Printing expr.left shows the nesting. The
Add at the root holds a Mul, which
holds a Num and a Var. The
print() at [1] evaluates that same
expr twice, once with x=3 and once
with x=10. Building 2 * x + 1 does not
compute a number. It builds a tree, so expr is a
value you can pass to evaluate() under different
variable bindings, as many times as you like. An unbound
variable raises a KeyError, naming the
variable.
**env gives the call site
evaluate(expr, x=3) rather than
evaluate(expr, {"x": 3}), and that convenience has
a memory cost. Each recursive call packs a fresh dict from
**env, so at any moment one dict is live per level
of recursion, and the live entries total the tree’s depth times
the number of bound variables. The cost matters most on the deep
trees about which this chapter warns later, which can run
thousands of levels.
**env is also why the / is there.
The / makes e positional-only,
which keeps the parameter name out of the variable namespace, so
an expression can use e as a variable.
e=5 goes into env. A
dict[str, int] parameter passes the same bindings
by reference at every call, and it would spare both the
/ and this explanation. This chapter keeps
**env for the call site.
The test file confirms that:
- A
Numevaluates to its value and aVarto its binding. - The operators build the tree you write by hand, with the integer on either side.
- One tree evaluates under different bindings.
- An unbound variable raises a
KeyErrorthat names the variable. ebinds as a variable, though it isevaluate()’s first parameter.
# test_evaluate.py
import pytest
from evaluate import evaluate
from expr import Add, Mul, Num, Var

def test_literal_and_variable() -> None:
    assert evaluate(Num(42)) == 42
    assert evaluate(Var("x"), x=3) == 3

def test_operators_build_the_tree() -> None:
    x = Var("x")
    assert 2 * x + 1 == Add(Mul(Num(2), x), Num(1))
    assert 1 + x == Add(Num(1), x)
    assert x * x == Mul(x, x)

def test_one_tree_many_environments() -> None:
    area = Var("w") * Var("h")
    assert evaluate(area, w=2, h=3) == 6
    assert evaluate(area, w=10, h=10) == 100

def test_unbound_variable_raises_key_error() -> None:
    with pytest.raises(KeyError, match="y"):
        evaluate(Var("y"), x=1)

def test_e_binds_as_a_variable() -> None:
    assert evaluate(Var("e"), e=5) == 5
New Operations, Same Tree
Evaluation has no privileged status. Rendering the tree as an infix string is another function, in another file, and the node classes stay unchanged:
# infix.py
from typing import assert_never
from expr import Add, Expr, Mul, Num, Var

def to_infix(e: Expr) -> str:
    match e:
        case Num(value):
            return str(value)
        case Var(name):
            return name
        case Add(left, right):
            return f"({to_infix(left)} + {to_infix(right)})"
        case Mul(left, right):
            return f"({to_infix(left)} * {to_infix(right)})"
        case _:
            assert_never(e)

if __name__ == "__main__":
    x = Var("x")
    print(to_infix(2 * x + 1))
    print(to_infix((x + 1) * (x + 2)))
#: ((2 * x) + 1)
#: ((x + 1) * (x + 2))
to_infix() walks the same tree that
evaluate() walks, from the same
2 * x + 1:
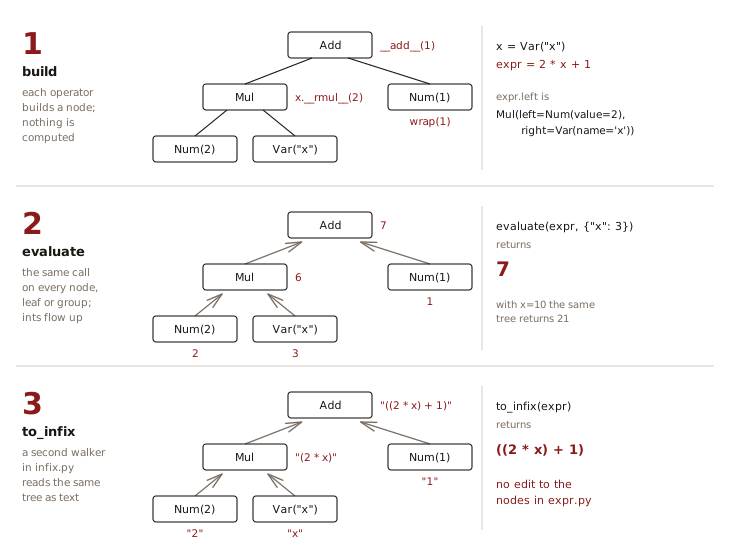
Side by side, the two walks share their shape. Each makes one
call per node, leaf or group, and each node’s result flows up to
its parent. Only the value a node returns differs, an
int in one walk and a str in the
other. The tree carries no meaning of its own, so a new
operation is one more walker.
Adding to_infix() without editing a node class
is the ability Visitor exists to
provide: new operations over an existing hierarchy, defined
outside it. The match version needs no
accept() method and no visitor classes. Unlike
singledispatch, it binds the nodes’ fields in the
patterns.
Simplification Rewrites the Tree
An interpreter need not produce a number or a string. It can
produce another tree. simplify() applies algebraic
identities. Adding zero or multiplying by one returns the other
operand, multiplying by zero returns Num(0), and
constant subtrees fold into a single Num. Each rule
is a nested pattern over a pair of already-simplified
children:
# simplify.py
from typing import assert_never
from expr import Add, Expr, Mul, Num, Var

def simplify(e: Expr) -> Expr:
    match e:
        case Num(_) | Var(_):
            return e
        case Add(left, right):
            lhs, rhs = simplify(left), simplify(right)
            match (lhs, rhs):
                case (Num(0), other) | (other, Num(0)):
                    return other
                case (Num(a), Num(b)):
                    return Num(a + b)
                case _:
                    if lhs is left and rhs is right:
                        # Share the unchanged subtree
                        return e
                    return Add(lhs, rhs)
        case Mul(left, right):
            lhs, rhs = simplify(left), simplify(right)
            match (lhs, rhs):
                case (Num(0), _) | (_, Num(0)):
                    return Num(0)
                case (Num(1), other) | (other, Num(1)):
                    return other
                case (Num(a), Num(b)):
                    return Num(a * b)
                case _:
                    if lhs is left and rhs is right:
                        return e
                    return Mul(lhs, rhs)
        case _:
            assert_never(e)

if __name__ == "__main__":
    from infix import to_infix
    x = Var("x")
    messy = 1 * x + 0 * Var("y") + (Num(2) + 3) * x
    print(to_infix(messy))
    print(to_infix(simplify(messy)))
#: (((1 * x) + (0 * y)) + ((2 + 3) * x))
#: (x + (5 * x))
messy writes Num(2) + 3 rather than
the plainer 2 + 3 on purpose. With
2 + 3, both operands are plain int, so
Python adds them to 5 before any node exists.
simplify() would receive 5 * x with
the fold already done. Num(2) is a node, so
+ dispatches to Operators.__add__()
and builds an Add for simplify() to
fold back down. 2 + 3 shows the limit of using the
host parser. An operator builds a node when either operand is
one, and does plain arithmetic otherwise.
The patterns read like the algebra they implement.
(Num(0), other) | (other, Num(0)) says “zero on
either side, keep the other side.” Both alternatives bind
other, and they must. Every alternative
in a | must bind the same set of names, so binding
left in one and right in the other is
a SyntaxError when the module compiles rather than
an unbound name at runtime. (Num(a), Num(b))
captures two constants for folding. The same syntax does two
opposite jobs: Num(0) after case is a
pattern that Python matches without calling Num,
and Num(0) after return is a
constructor call.
Matching the pair of simplified children, rather than the
original node, lets the rules compose. A
case Add(Num(0), other) at the top of the function
tests the tree as the caller wrote it, so
(0 * y) + x keeps its zero. The left child is a
Mul until something simplifies it into a
Num. Simplifying both children first, then matching
the results, applies the rule to the Num(0) the
recursion just produced. That order is how the demo’s
((1 * x) + (0 * y)) collapses to
x.
A record blocks every field assignment, so
simplify() cannot edit its input.
simplify() returns a new tree that shares unchanged
subtrees with the original. The is guard in each
case _ returns the node it received when both
children simplified to themselves. The guard tests identity with
is rather than equality with ==.
Sharing means the same object, and is answers with
one comparison, where a record’s == compares fields
and descends into any subtree that changed.
The test file confirms that:
- Adding zero or multiplying by one returns the other operand.
- Multiplying by zero returns
Num(0). - Constant subtrees fold into one
Num. - The rules apply at every level of the tree.
- An expression with nothing to simplify comes back as the same object.
- The result shares an unchanged subtree with the input.
# test_simplify.py
from typing import Final
import pytest
from expr import Expr, Mul, Num, Var
from simplify import simplify

X: Final[Var] = Var("x")

@pytest.mark.parametrize("expr, expected", [
    (X + 0, X),
    (0 + X, X),
    (1 * X, X),
    (X * 1, X),
])
def test_identity_returns_other_operand(
    expr: Expr, expected: Expr,
) -> None:
    assert simplify(expr) == expected

def test_multiplying_by_zero_gives_zero() -> None:
    assert simplify(X * 0) == Num(0)
    assert simplify(0 * X) == Num(0)

def test_constant_folding() -> None:
    assert simplify(Num(2) + 3) == Num(5)
    assert simplify(Num(2) * 3 + 4) == Num(10)

def test_rules_compose() -> None:
    assert simplify((X + 0) * (1 * X)) == Mul(X, X)

def test_already_simple_is_unchanged() -> None:
    expr = 2 * X + 1
    assert simplify(expr) is expr

def test_unchanged_subtrees_are_shared() -> None:
    keep = Var("w") * Var("h")
    assert simplify(keep + 0 * Var("z")) is keep
Three walkers over one set of nodes is the pattern pair in
full. Composite is the data: a union of node types,
some holding others. Interpreter is the behavior:
recursive functions that give the tree meaning. Python
compresses the pair into records, a union, operator methods that
build nodes, and match functions that walk
them.
One practical limit applies. Every function here recurses once per level of tree, and Python’s recursion limit (roughly a thousand frames) caps how deep a tree they can walk. Realistic expressions stay far below it. A machine-generated chain of thousands of nested nodes exceeds the limit. The alternative is an iterative walk with an explicit stack of pending nodes.
A Template Is a Tree
Python has a composite of its own and supplies no walker for
it, so the walker is yours to write. A t-string
evaluates to a Template: a stream of two node
kinds, the literal str pieces the author typed and
the Interpolation objects holding the values.
Iterating over a Template is flat.
for piece in template yields exactly one level of
str and Interpolation objects, so the
walk is a loop rather than a recursion. An interpolation’s value
can be a Template, built by nesting one
t-string inside another. +
concatenates t-strings into one flat
Template, as the query in the listing
below shows, so nesting is the one way to produce a
Template-valued interpolation. A walker that loops
over the top level must therefore also recurse into any value
that is a Template. Everything else follows this
chapter’s walkers: one branch per node kind, and a recursive
call where a node holds more nodes.
Iterating over a Template produces
str | Interpolation, a closed union like
Node with two members, so an
isinstance() test narrows it as well as a
match does. The else paired with
isinstance(piece, Interpolation) is the
str case. Iteration skips the empty literal pieces,
so t"{a}{b}" yields two Interpolation
objects and no strings. template.strings keeps the
empty slots when the alternation matters. The structure is data,
and its meaning is whatever a function computes from it:
# template_query.py
from string.templatelib import Interpolation, Template

def to_query(
    template: Template) -> tuple[str, list[object]]:
    sql: list[str] = []
    values: list[object] = []
    for piece in template:
        if isinstance(piece, Interpolation):
            if isinstance(piece.value, Template):
                nested_sql, nested_values = (
                    to_query(piece.value))
                sql.append(nested_sql)
                values.extend(nested_values)
            else:
                sql.append("?")
                values.append(piece.value)
        else:
            sql.append(piece)
    return "".join(sql), values

def to_shape(template: Template) -> str:
    parts: list[str] = []
    for piece in template:
        if isinstance(piece, Interpolation):
            parts.append(f"<{piece.expression}>")
        else:
            parts.append(piece)
    return "".join(parts)

name = "Alice'; DROP TABLE users; --"
limit = 18
query = (t"SELECT name FROM users WHERE name={name} "
         + t"AND age>{limit}")
sql, values = to_query(query)
print(sql)
#: SELECT name FROM users WHERE name=? AND age>?
print(values)
#: ["Alice'; DROP TABLE users; --", 18]
print(to_shape(query))
#: SELECT name FROM users WHERE name=<name> AND age><limit>

inner = t"a={limit}"
outer = t"SELECT * FROM t WHERE {inner}"
sql2, values2 = to_query(outer)
print(sql2)
#: SELECT * FROM t WHERE a=?
print(values2)
#: [18]
to_query() and to_shape() stand in
the same relationship as evaluate() and
to_infix(): two operations over one structure that
mentions neither of them. Adding a third changes none of the
existing code.
outer interpolates inner, another
Template, rather than a plain value.
to_query() checks for that case and recurses, so
inner’s pieces flatten into the same
sql string and values list. Every
entry in values2 is then a value a database driver
accepts. Composing t-strings this way builds a
nested composite. Iterating over any one Template
stays flat.
to_query() uses the walk to keep user values out
of the query text. name holds an injection attempt,
and it comes out as a value in the parameter list rather than as
text in the query. The reason is structural rather than clever.
to_query() receives the literal pieces and the
values separately, so values stay out of the sql
list. Written as an f-string, the same line is one finished
str with the attack inside it. Any defense must
then inspect that string and guess where the user’s text
begins.
That separation is the general argument for handing a consumer the structure instead of the answer. A finished string no longer records which characters the program wrote and which a user did, and the safety decision depends on that distinction. Textbooks usually present the Interpreter pattern as a way to evaluate sentences in a small language. Here it keeps a decision available to whoever should make it.
Exercises
This chapter’s solutions give a hint, usually the shape of the code, and a full answer for each exercise.
- Add
find(entry, name)tofilesystem.py: a generator yielding the path of every entry whose name matches. A directory can match, and matching should continue into it. - Add a
Symlinknode to theNodeunion infilesystem.py, holding a name and a target path, and let the type checker report every operation that must change. Decide whatdisk_usage()andwalk()should do with a link. - Add
Neg(negation) andDiv(division) nodes toexpr.py, along with__neg__()and__truediv__()operator methods. Updateevaluate(),to_infix(), andsimplify(). What shouldsimplify()do with division byNum(0)? to_infix()parenthesizes every operation. Rewrite it to emit only the parentheses that precedence requires, so2 * x + 1renders as2 * x + 1but(x + 1) * (x + 2)keeps its parentheses.- Write
derivative(e, name): a function that returns the symbolic derivative of an expression with respect to a variable, using the sum rule and the product rule. Run its results throughsimplify()and compare. - At runtime,
"a" + xsilently buildsAdd(Num("a"), x), an ill-typed tree the type checker rejects in source it can see. Rewrite all four operator methods to returnNotImplementedfor an operand they cannot use (Multiple Dispatching shows the idiom), and confirm that"a" + xandx + "a"both now raise aTypeError. - Write a third walker over
Templateintemplate_query.py,to_html(), that emits the literal pieces unchanged and replaces<,>, and&in every interpolated value with their HTML entities. Show thatt"<p>{comment}</p>"survives acommentcontaining a<script>tag. - Build a left-deep expression by folding
+over a few thousandNumnodes, and confirm thatevaluate()raises aRecursionError. Then writeevaluate_iterative(), which walks the same tree with an explicit stack and no recursion, and check that the two agree on a small expression. Raising the limit withsys.setrecursionlimit()also avoids the error. Say what it costs. - A plugin package needs to add its own entry types to
filesystem.pywithout editing your code. Sketch what breaks, then write the version ofdisk_usage()that supports the plugin’s entry types. Which of the two designs, amatchover a union or a method on a base class, would you use for a file system, and which for the expression language inexpr.py?